Claude Code Session Management with Emoji Status Prefixes
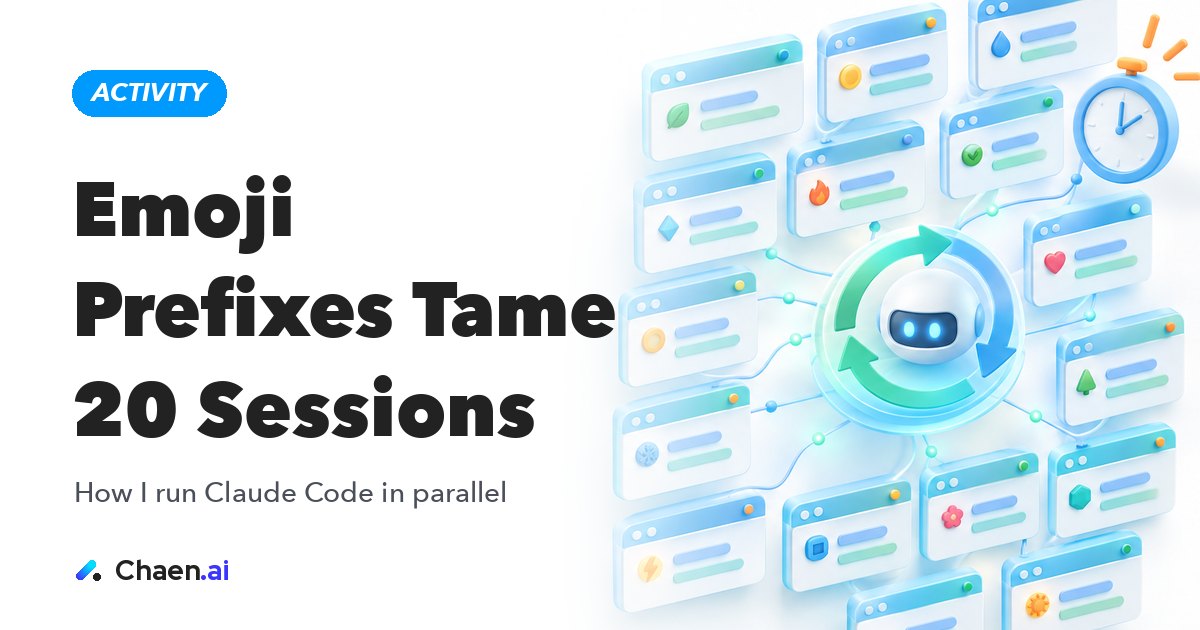
Claude Code session management with emoji status labels: every 15 minutes Claude reads each session's last exchange and relabels it. 20 stay readable.
I run 15 to 20 Claude Code sessions at the same time. The only mechanism that makes it workable is this: every 15 minutes, Claude reads the last exchange in every session and rewrites the emoji at the front of the session name. This post covers how I split the states, why the interval is 15 minutes, and why the automation is allowed to touch nothing but the name. I released the setup for free and it is on GitHub.
The real bottleneck in Claude Code session management
When you add sessions, the first thing you feel is speed. Then something else runs short. For me it was attention, not capability.
With fifteen sessions live, the state of the world looks like this. One is waiting on a decision only I can make. One has a draft finished and just needs to be sent. One is still working. And in the session list, all three look identical: rows with names. So I opened them top to bottom, read the last exchange, reconstructed where each one was, and closed it again. That re-orientation pass was eating more of my day than the actual work.
What I needed was not a progress bar and not notifications. I needed the list itself to tell me which single session to touch next. When you run AI in parallel, the ceiling is not model throughput. It is the point where a human can no longer hold the state of everything in their head.
Five emoji states, and why the split matters
I use five:
- 🔴 needs my judgment
- 📤 draft is ready, just send it
- 👀 under review
- ⏳ working
- ✅ done
The axis is simple. Does this need a human, and if so, what kind of human effort does it need?
Why 🔴 and 📤 are separate
Collapsing these two destroys the whole point. A 📤 item means skimming the output and sending it, which takes tens of seconds. I can clear those standing in a station. A 🔴 item means reading, thinking, and deciding, which needs a real block of time and a clear head.
If both wear the same label, all you get is a pile called “needs a human,” and you still cannot tell what is actionable right now. Split by the cost of the human effort, and a spare five minutes becomes a 📤 sweep, while a protected hour becomes a 🔴 queue.
⏳ and 👀 mark what not to touch
Neither of these is my turn. The value of labeling them is the permission not to open them. If the goal is to cut re-orientation work, a label that reliably means “nothing for you here” is worth as much as one that calls you in.
✅ accumulates as a close-out pile, which means cleanup becomes something I schedule instead of something I trip over.
Why Claude relabels the names every 15 minutes
The usual way status labels die is that a human has to maintain them. State changes while you are not looking. The thing that was running has finished; the thing you thought was finished has come back with a question. A hand-maintained label is always slightly stale, and once people learn it is stale, they stop reading it.
So Claude does the relabeling. It reads the last exchange in each session, decides which state that exchange looks like, and rewrites the leading emoji in the name.
Only the last exchange gets read
There is no reason to feed in full history. The only question is whose turn it is right now, and the answer to that is visible in the last exchange. Keeping the read window minimal makes the judgment fast and makes running it repeatedly cheap.
Why 15 minutes
Shorter and the labels never settle: the list reshuffles every time you glance at it, which trains you to distrust it. Longer and you start acting on stale information. Fifteen minutes matches the natural grain of my own work, so when I come back from one block of focus, the list in front of me is current.
Let the model read, don’t write exhaustive rules
I could try to encode “if these conditions, then this state.” Letting Claude read the last exchange and pick a state is more robust. Conversations end in too many shapes: with a question, with a deliverable, mid-step, with an error. Anything you can tell by reading a few lines of prose is a bad fit for a decision tree, because the exceptions win.
Renaming is the whole surface area
This automation never touches session contents. It changes one emoji at the front of a name. Nothing else.
That is a design decision, not laziness. When you put automation inside your own working loop, you want to decide the worst case up front. If names are the only writable surface, then the worst a misjudgment can do is show the wrong label. I find out the moment I open the session, and the next pass corrects it. No work gets damaged.
Because the downside is bounded, I can trust the labels. Because I trust them, I stop opening everything to check. That is where the productivity actually came from. Automation pays off less by making decisions for you and more by enlarging the set of things you no longer need to verify.
What this means for AI adoption in Japan
In Japanese companies, I keep hearing a version of “we deployed AI and productivity didn’t move.” In my experience the cause is rarely the quality of the model’s output. The jam is downstream: nobody can see where the human review queues are or how long they have become. Japanese organizations tend to be strong at reporting progress through people, and that habit quietly hides the queue when the work shifts to one person supervising many agents.
That is the structural point. The moment one person is driving many AI sessions, review backlogs multiply while becoming less visible. Turning state into a label you can read from the list is the smallest tool I know for handling that backlog.
One practical note for rolling this out internally: build the labels around “which item needs a human right now,” not “what is the AI doing.” The first phrasing is already the language of operations, so it survives contact with people who do not care about the tooling.
There is a matching lesson for AI and tech companies trying to land in the Japanese market. Explaining raw capability tends to stall at “impressive, but we don’t know how we’d run it.” Japanese buyers can picture a rollout once you answer three things: how many of these one person can supervise, who checks the output and at what point, and what breaks when the system is wrong. Those three answers are what turn a demo into an internal proposal.
How to try it on your own stack
You do not need my five emoji. If your work is different, both the number of states and their meanings should change. The sequence is what transfers:
- Write out roughly five states your work actually passes through. Many more than that and you stop distinguishing them at a glance.
- Split “needs a human” by the cost of that human effort. Never let a thirty-second send sit under the same label as a decision that needs an hour.
- Start the automatic rewriting on something recoverable, like names or titles, not on the work product.
- Match the refresh interval to how often you actually come back to the list.
The cheapest way to know whether this applies to you is to time yourself: open your current list of sessions, tasks, or tickets, and count the seconds it takes to decide which one to work on next. Multiply that by how many times a day you do it. If that number is uncomfortable, this approach will pay for itself, and the setup is on GitHub if you want to start from mine.
FAQ
How many Claude Code sessions can you run at once?
I run 15 to 20 at the same time. The ceiling is not the tooling but whether a human can still tell which session to open next, which is exactly what the emoji labels solve.
Do you update the emoji prefixes yourself?
No. Claude does it every 15 minutes by reading the last exchange in each session and rewriting only the emoji at the front of the name. I just read the names.
Is the setup available to use?
Yes, I released it for free and it is on GitHub. The five states are mine, so adapt the meanings to your own work before adopting them.
Based on a post on XOriginal post ↗
About the author
CEO of DigiRise Inc. Has supported 600+ companies and 50,000+ people with AI training, consulting and development. GMO AI & Crypto advisor, Google Gemini AI advisor. 200K+ followers on X.
Related articles
 PHP Vulnerability Response in Japan: Closing the Gap Oct 21, 2026
 How to Book an AI Speaker in Japan: Criteria and Process Oct 21, 2026
 Japan Social Media and AI News: X, YouTube, LINE, note Oct 19, 2026
 Weekly AI News Roundup: Gemini 4 Argon and DeepSeek V4.1 Oct 18, 2026
 Tesla New Roadster Demo: What the Reveal Gets Right Oct 16, 2026
 Press Release Distribution in Japan: Services and Media Oct 14, 2026